
AI-Driven Automation
for Finance & Beyond
Building production-grade systems that combine machine learning, real-time data processing, and cloud infrastructure to solve complex problems at scale. Forward-deployed with client teams: discovery to production on your infrastructure, cloud or fully on-premises, ending in documented handover rather than a slide deck.
Embedded client delivery: discovery, architecture, build, production deployment on the client's own infrastructure (cloud or fully on-premises), and documented handover. Client identities and data are withheld by agreement; the architectures below are the real systems, running in production today.
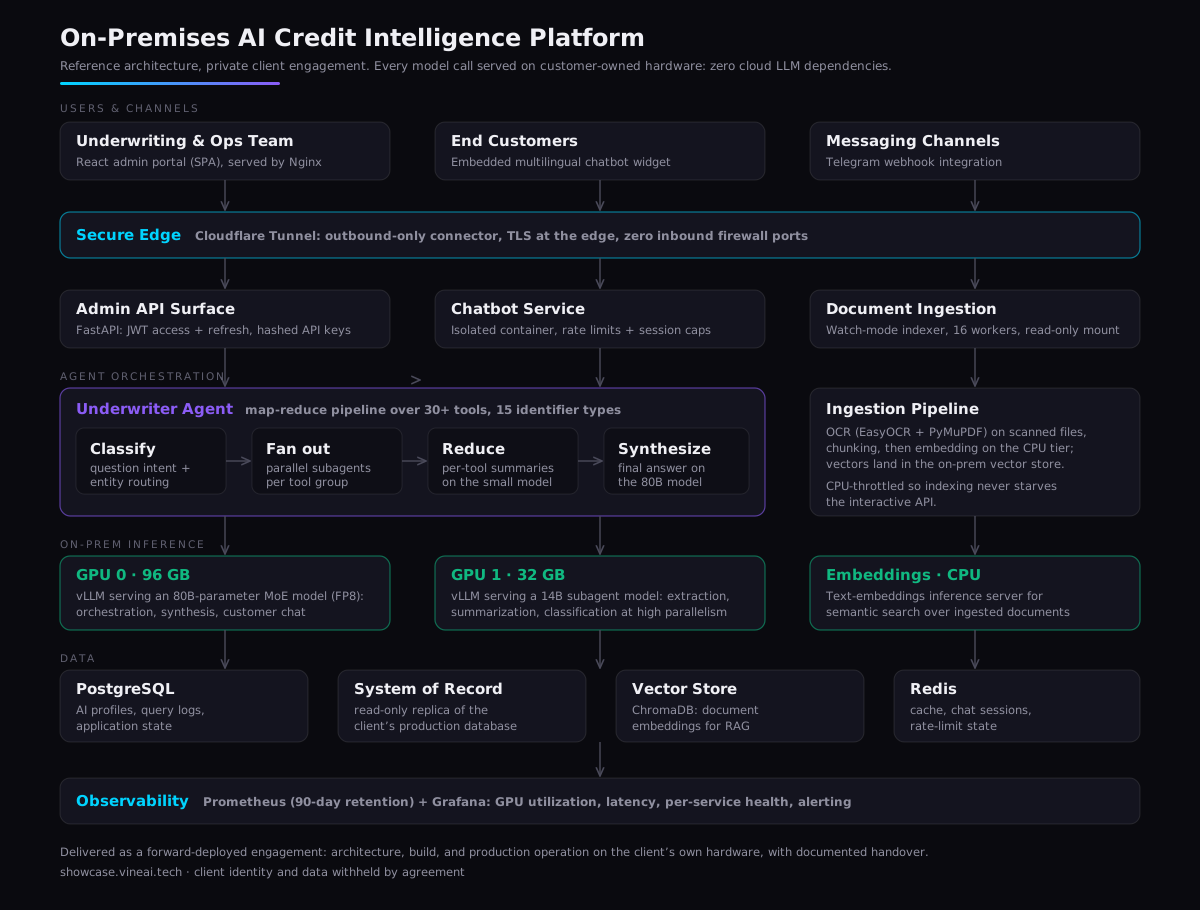
AI Credit Intelligence
On-premises AI platform for B2B credit analysis and risk assessment, delivered forward-deployed on the client's own hardware. Dual-GPU inference (RTX PRO 6000 96GB + RTX 5090 32GB), 30+ tool underwriter agent with map-reduce pipeline, multilingual customer chatbot, and zero cloud LLM dependencies: no customer data ever leaves the building.
🔒 Private client · Reference architecture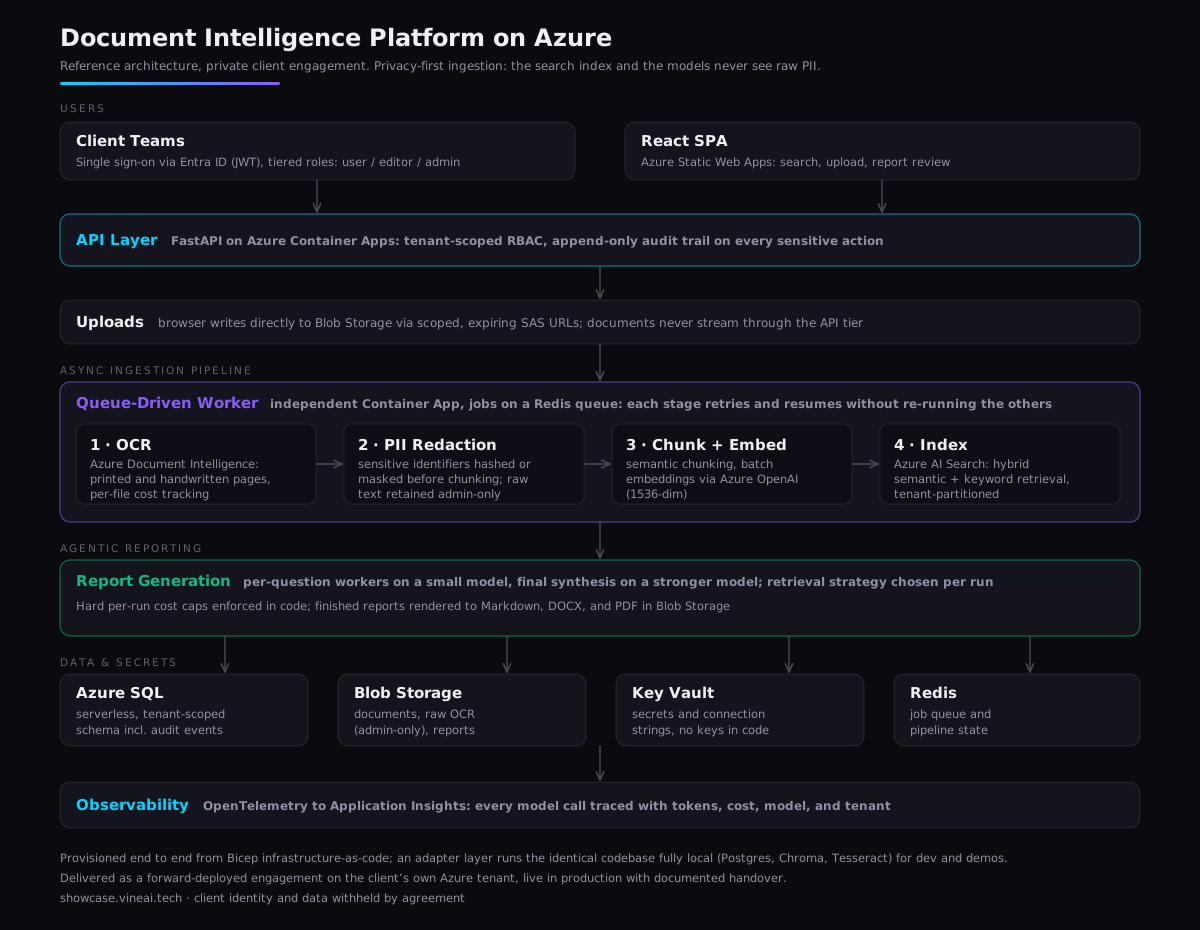
Document Intelligence
AI document intelligence platform live in production on a private client's Azure tenant, provisioned end to end from Bicep infrastructure-as-code. OCR of printed and handwritten documents with PII redaction before anything is indexed, semantic search over large collections, and cost-capped agentic report generation; multi-tenant with Entra ID RBAC and a full audit trail.
🔒 Private client · Reference architecture
Site Replatform + AI Assistant
Moved a client's public site off a hosted website builder onto managed static hosting, working inside hard constraints: the registrar would not move and the incumbent builder would not delegate nameservers, so hosting was selected to fit two DNS records the client can edit themselves. Hand-written responsive HTML/CSS rebuilt from the live site, a retrieval-grounded AI assistant trained on the client's own content embedded as a drop-in widget, and handover via a branded runbook PDF covering the DNS cutover and billing transitions.
🔒 Private Client Engagement
NVIDIA AI Factory
A 48-page technical specification for an air-gap-capable, multi-tenant on-premises AI factory built on NVIDIA AI Enterprise. One shared GPU pool serves interactive R&D, distributed NeMo training, and governed NIM/Triton/TensorRT-LLM inference behind a self-service, policy-governed control plane: Run:ai/KAI scheduling, MIG and fractional-GPU partitioning, NeMo Guardrails, and an air-gapped GitOps lifecycle that lifts GPU utilization from ~15–35% toward 70%+. Architecture design document.
Architecture spec (PDF)
vllmstat
“nvtop for vLLM”, a zero-infrastructure terminal dashboard that scrapes vLLM's /metrics endpoint for real-time concurrency, throughput, and latency percentiles. GPU monitoring across NVIDIA/AMD/Intel, KV-cache hit rates and compression, speculative-decoding acceptance, and multi-instance fleet drill-down, with no Prometheus/Grafana stack required. Open source (Apache-2.0), pip install vllmstat.
 github.com/bryanvine/vllmstat
llamastat
The llama.cpp counterpart to vllmstat: a terminal dashboard over llama-server's read-only endpoints showing per-slot phase, task, and context-window usage live. It diffs the server's own slot token counters between polls, so generation and prompt tokens/s are visible even on servers started without the Prometheus endpoint, and adds host telemetry the server never exposes: CPU load, memory, per-chip hwmon temperatures, and package power differenced from RAPL energy counters. Open source (Apache-2.0), pip install llamastat.
 github.com/bryanvine/llamastat
AI Router
Self-hosted LLM gateway unifying multiple on-prem vLLM hosts behind one chat UI and OpenAI-compatible API. Automatic failover routing across GPU backends with per-user usage analytics and spend tracking.
ai-router.vineai.tech
Vine AI
Adaptive on-premises intelligence platform that deploys on your infrastructure with zero cloud dependencies. Industry-native configurations for healthcare, legal, fintech, and more with multi-source data analysis and white-label support.
vineai.tech
gpt-oss-120b Expert Pruning
Task-calibrated expert pruning of OpenAI's 117B-parameter MoE: 128 → 48 experts per layer (62.5% removed), shrinking the checkpoint from 65 GB to ~27 GB so it serves on a single 32 GB GPU at 128k context in stock vLLM. Calibrated on the full model's own generation traces from a production scoring workload, it holds Cohen's κ 0.51–0.54 against stored production decisions, inside the unpruned model's own self-consistency range, at 100% strict-JSON parse; the prompt-only ablation collapsed to κ 0.15. Open weights on Hugging Face; it ran as a production shadow behind the unpruned model, re-scoring every live call without changing the result, until a distilled 8B took the slot on better agreement.
bryanvine.github.io/gpt-oss-pruning
Job-Scoring Task Distillation
The complementary route to the pruning work above: instead of cutting a 117B teacher down to fit a 16–32 GB GPU, take a model that already fits and teach it the one task. 15,810 training pairs reconstructed from a live scoring table against the exact production prompt, PII-scrubbed, with the frozen evaluation set excluded so the benchmark stays clean. QLoRA (rank 32, 14.3 hours on a single 16 GB RTX 4080 Super) on Qwen3-8B scores κ 0.64 against stored production decisions, against 0.51–0.54 for the 48-expert pruned 120B, at 100% strict-JSON parse and ~5× the speed. It has since replaced the pruned model as the live scoring shadow, tracking the full teacher more closely on every logged field. Apache-2.0.
bryanvine.github.io/job-score-distillation
Bare-Metal Social
A reference-architecture working paper for a Facebook/MySpace-scale social network on owned, homogeneous commodity hardware: a single 2U server SKU (32-core, 256 GB RAM, ~300 TB) that software assigns to any role: load balancer, app, cache, sharded SQL (Vitess), Ceph object storage, Kafka, or search. Its signature is a 2:2:1 witness topology: two active-active data centers plus a lightweight witness site, so any one site can fail without losing quorum or splitting brain. Temperature-tiered NVMe→HDD storage with cross-node erasure coding keeps cost-per-user predictable enough for a privacy-first, subscription-funded platform.
bryanvine.github.io/bare-metal-social
TurboQuant XPU
A research series on LLM inference performance on Intel Arc (Battlemage) GPUs: three write-ups plus deep R&D notes from porting TurboQuant KV-cache quantization (ICLR 2026) to Intel XPU for vLLM. Custom Triton→SPIR-V kernels (Walsh-Hadamard rotation + Lloyd-Max, 4–8× KV-cache compression), three native SYCL kernel attempts (ESIMD, joint_matrix), and TurboQuant + EAGLE3 speculative decoding on the Arc Pro B70, with full benchmarks and an honest record of what worked and what didn't.
bryanvine.github.io/turboquant-xpu
MLA-GPT
A controlled study of attention variants: MLA (DeepSeek's Multi-head Latent Attention) vs MHA, MQA, and GQA, training identical 124M GPTs from scratch (RoPE, SwiGLU, RMSNorm, PyTorch) where only the attention module changes, with a weight-absorption trick that avoids rematerializing KV heads at decode. Finding: MLA compresses the KV cache 5.6× vs MHA (359 tok/s @ 3.0 GB vs 258 @ 11.1 GB at 16k context) at ~negligible perplexity cost. Open source (MIT), single-GPU reproducible.
bryanvine.github.io/mla-gpt
JEPA Trader
Research feasibility study: “Does JEPA Find Alpha?” Applies Joint-Embedding Predictive Architectures (self-supervised representation learning) to four market modalities: limit-order-book microstructure, OHLCV bars, news sentiment, and funding-rate carry, with Transformer/PatchTST encoders and leakage-controlled walk-forward evaluation. Key finding: JEPA matches supervised encoders without labels, yet no net-of-cost edge survives transaction costs.
bryanvine.github.io/jepa-trader
Alpha Research
Cross-asset quantitative research program: a 7-paper series hunting genuinely harvestable alpha across crypto, equities, FX, commodities, and volatility, every backtest net of realistic costs and held to a fixed rigor bar (deflated Sharpe, PBO, purged walk-forward). Honest negative results are first-class. Capstone: the surviving edges combine via risk parity into a diversified 0.53-Sharpe book that beats the QSPIX benchmark.
bryanvine.github.io/alpha-research
AWS Trading Platform
A reference architecture for a systematic, AI-augmented trading platform on AWS: serverless-first and event-driven across Amazon SageMaker (quant ML lifecycle), Bedrock (risk-gated GenAI research + RAG), OpenSearch (vector retrieval), and Lambda (low-latency inference). Research is hard-isolated from live trading, every order passes a non-bypassable fail-closed pre-trade risk gate (SEC Rule 15c3-5), and every decision is reproducible to its exact model, feature snapshot, and code commit. Architecture design document.
Architecture spec (PDF)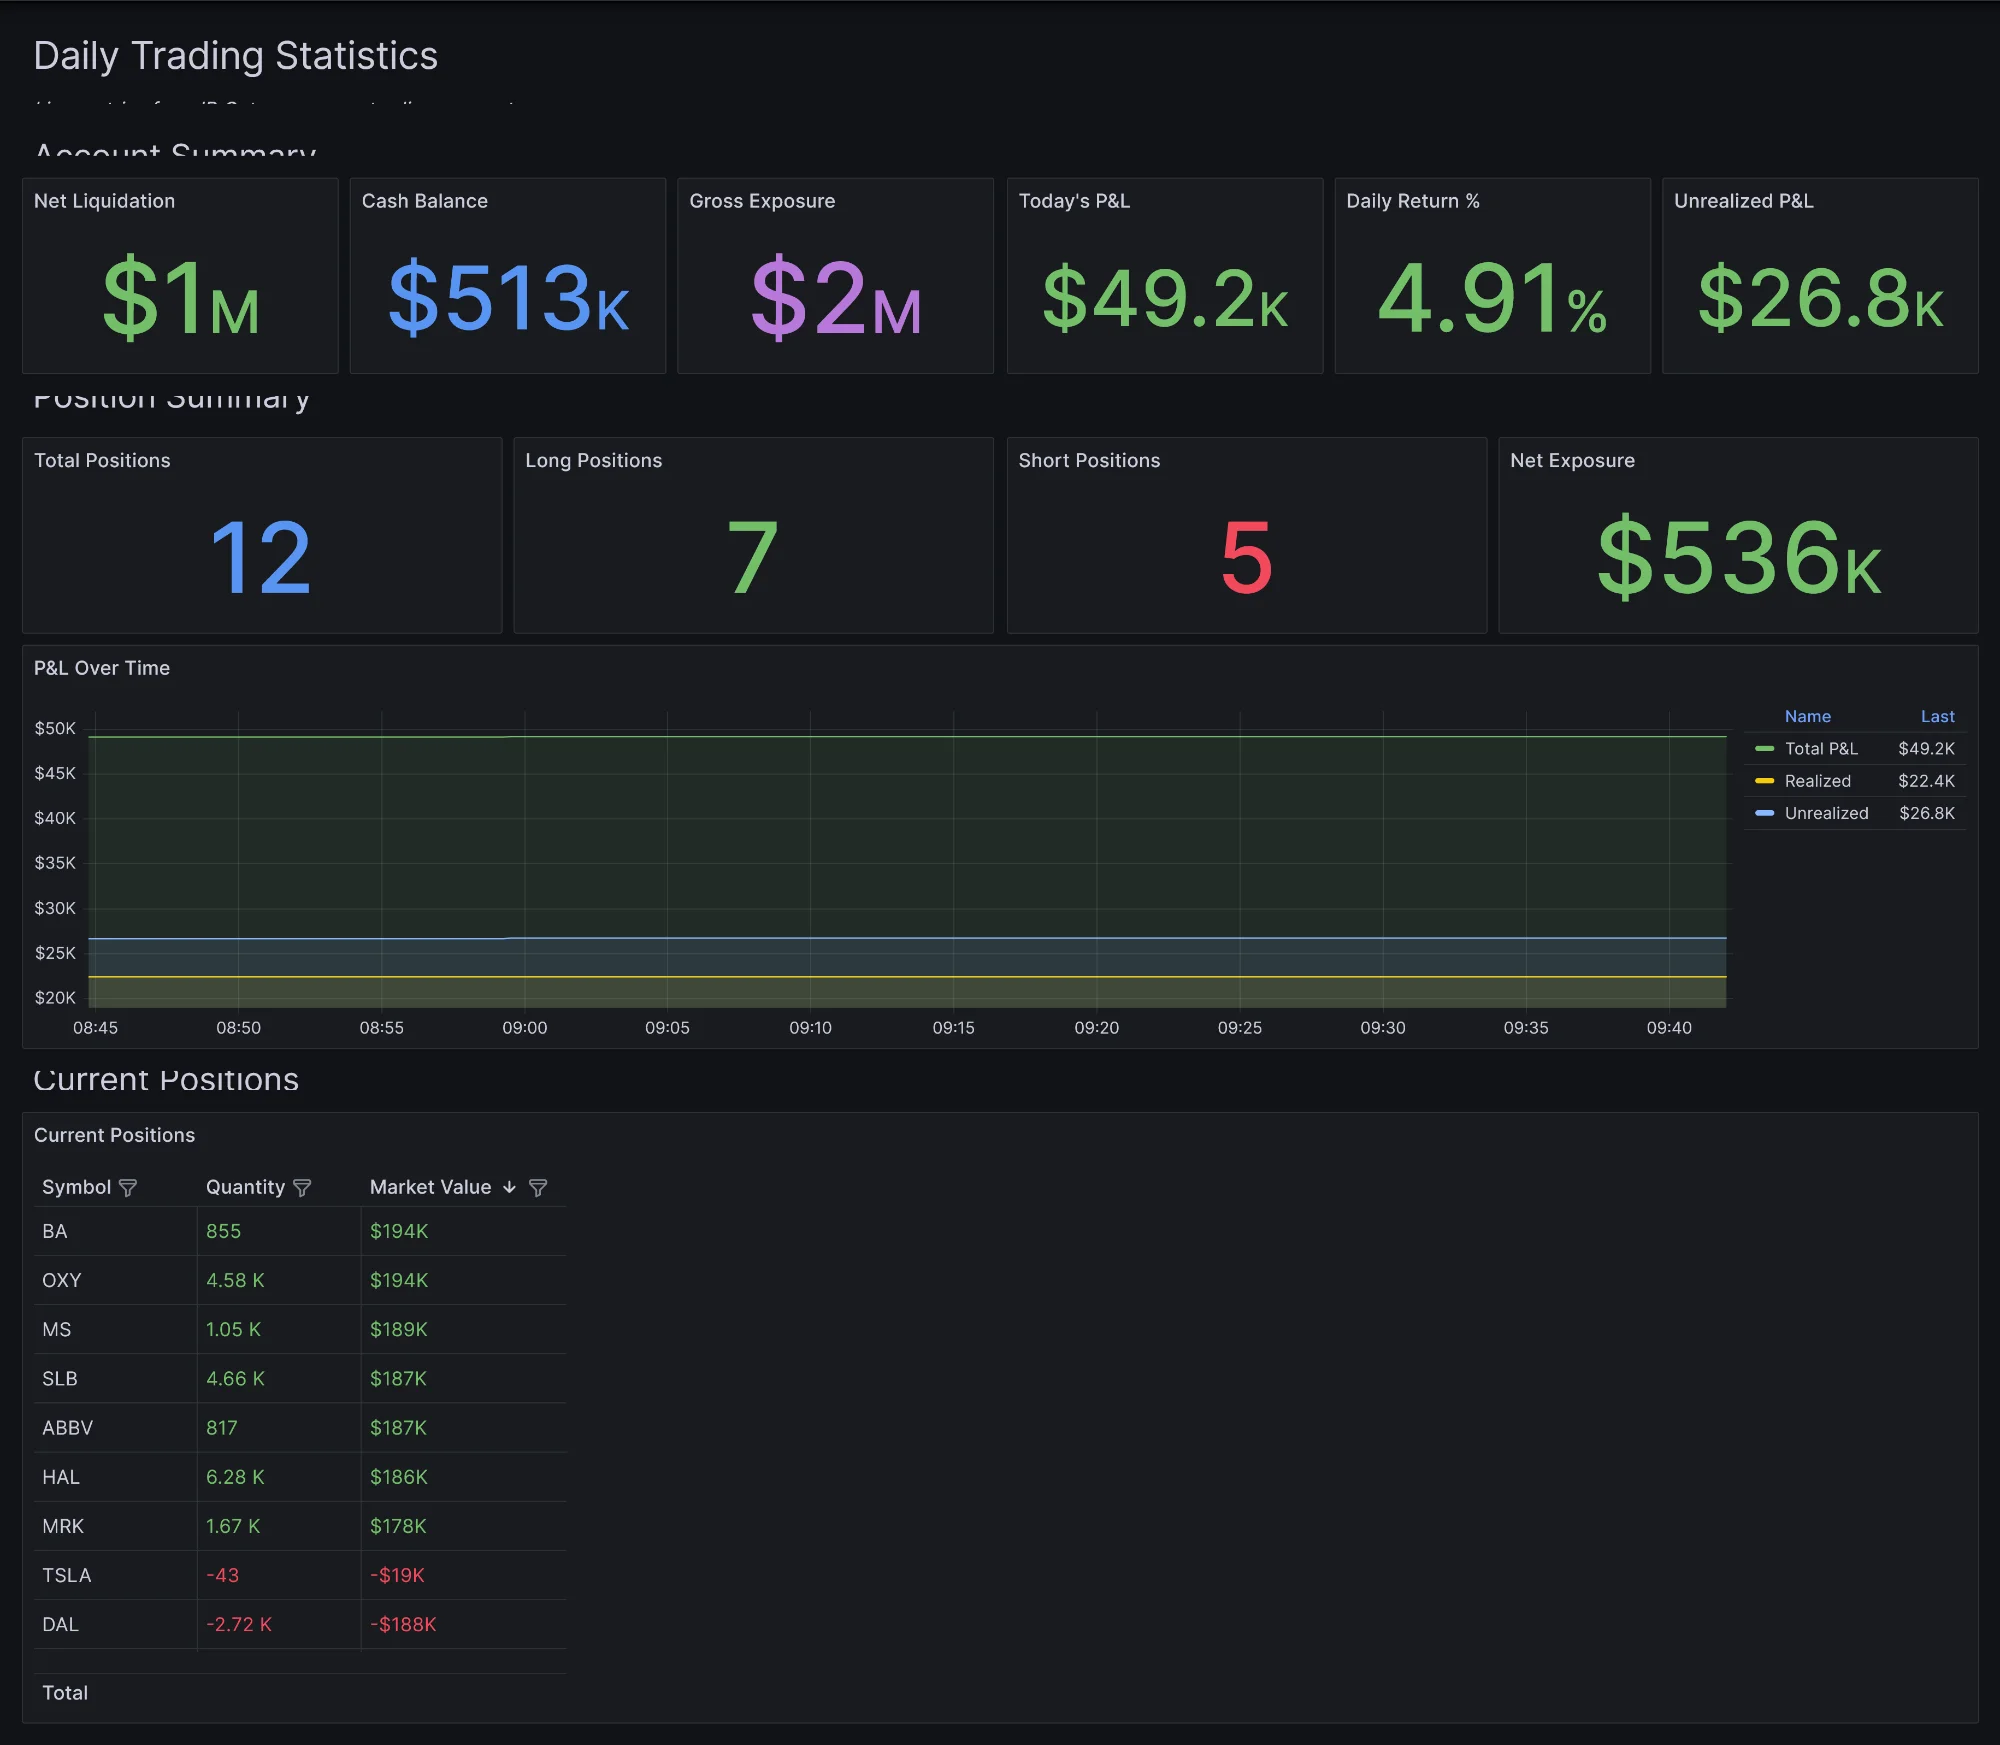
Algorithmic Trading
Medium-frequency trading system processing 500–2,000 securities with GPU-accelerated ML ensemble and LLM-powered news sentiment analysis.
trading.vineai.tech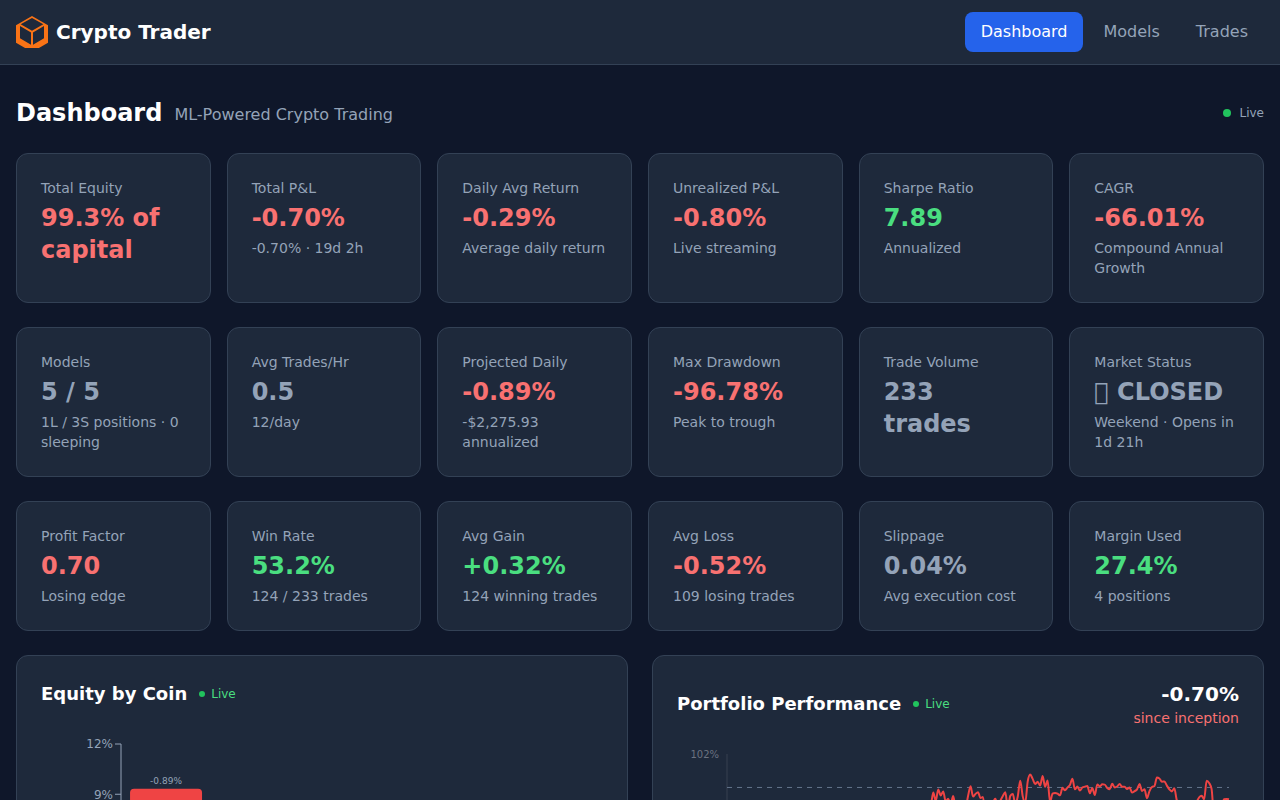
Crypto Trading
ML-powered cryptocurrency trading on Hyperliquid. LSTM and gradient-boosted models with walk-forward validation, dynamic capital allocation, and real-time execution during US market hours.
crypto.vineai.tech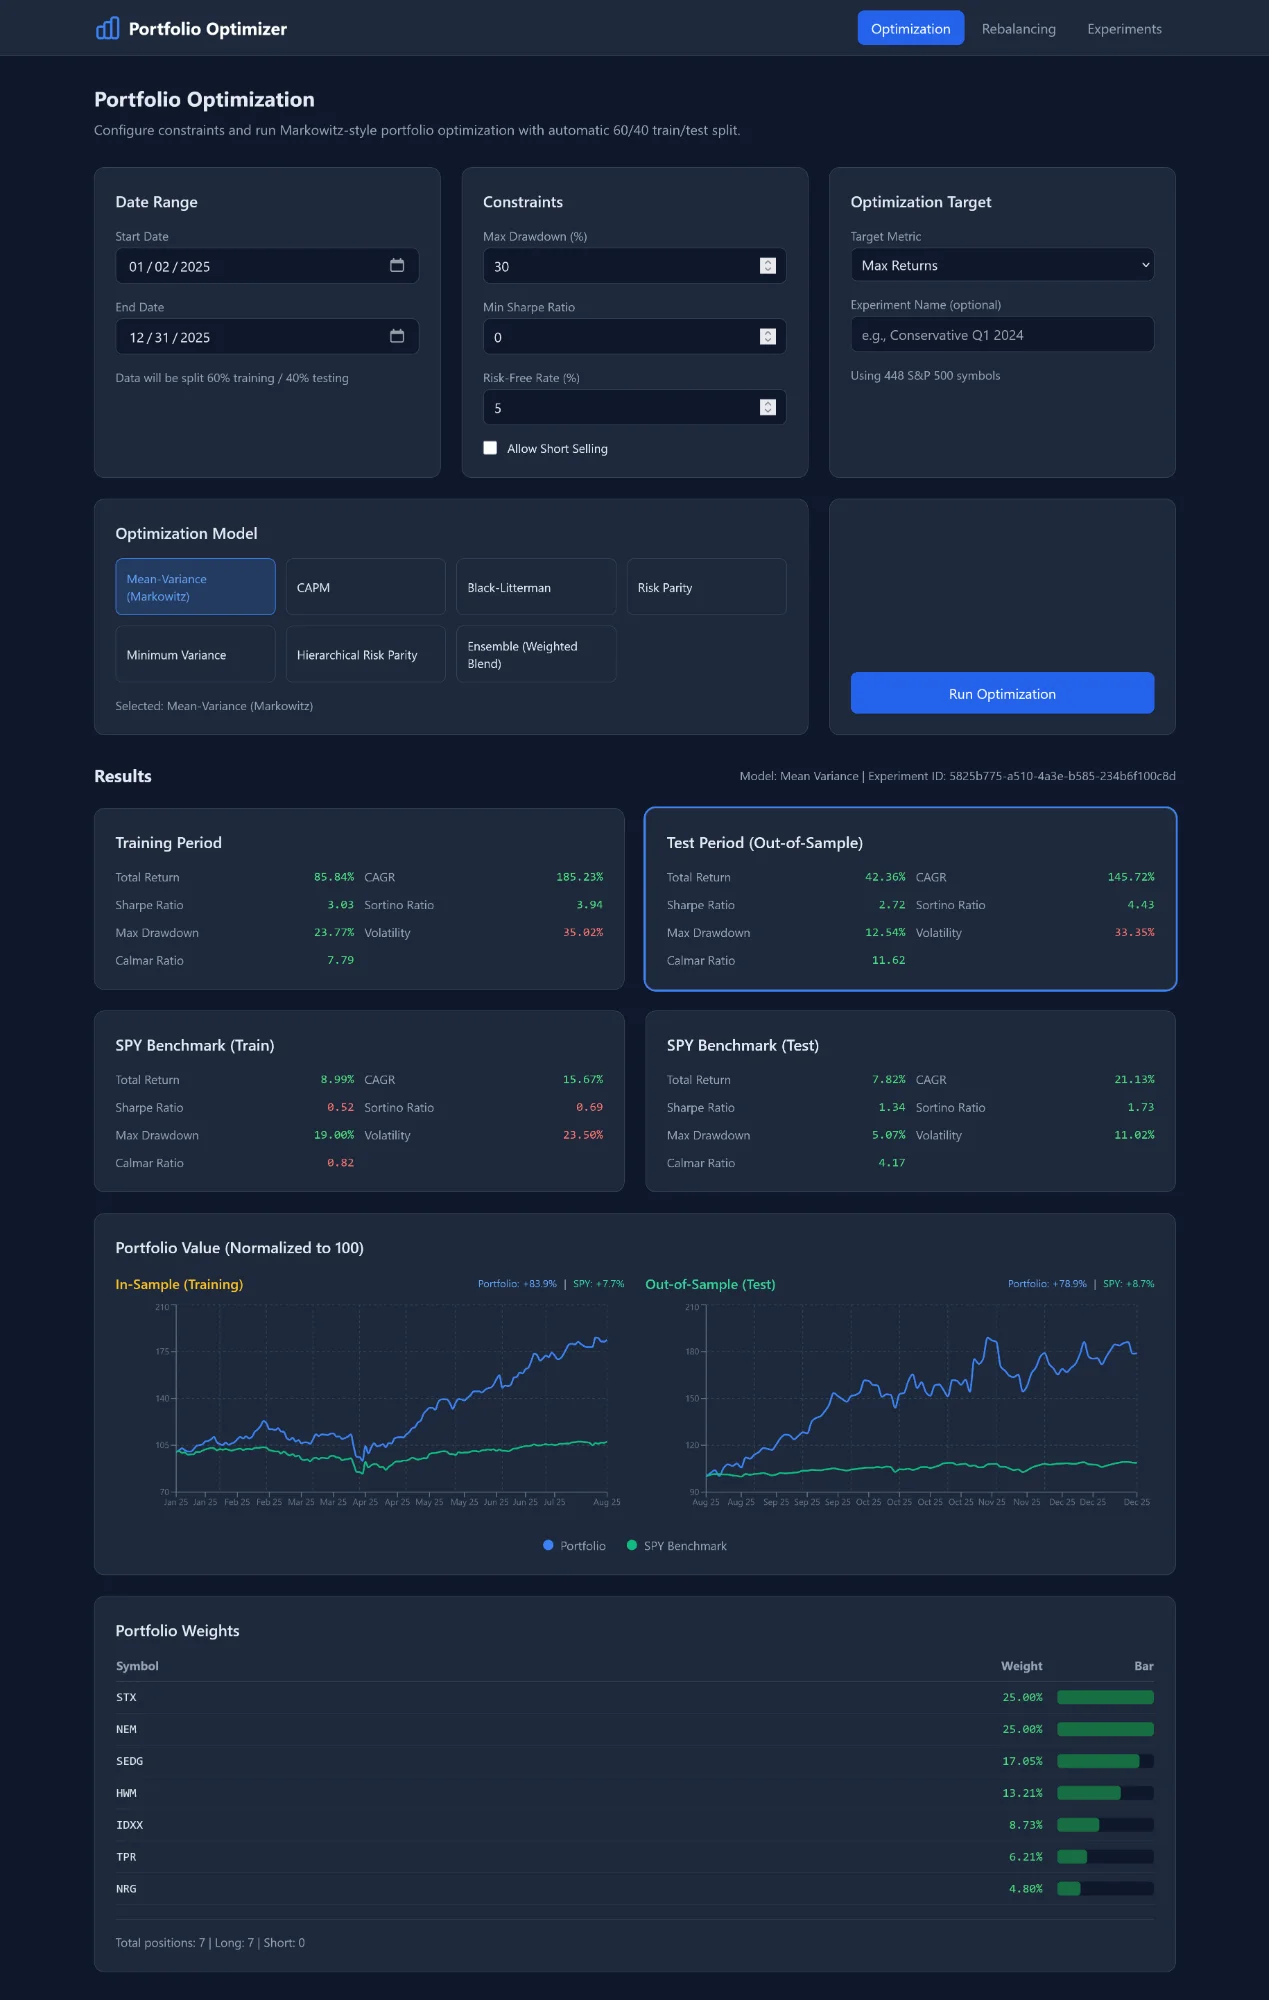
Portfolio Optimizer
Markowitz-style system with 8 optimization models, GPU-accelerated covariance estimation, and backtesting across the S&P 500 universe.
portfolio.vineai.tech
Damodaran Bot
Daily intrinsic-value (DCF) recommendations for a curated US large-cap universe, in the spirit of Aswath Damodaran: a credible business story drives the numbers, and Python, not the model, runs the discounted-cash-flow math, so every valuation is reproducible and auditable. Claude (Opus/Sonnet) writes the story and sets four value drivers as structured JSON; a deterministic FCFF engine returns intrinsic value, margin of safety, and BUY/HOLD/SELL. Research experiment, not investment advice.
dbot.vineai.tech
Buffybot
A Warren-Buffett-style quality investor, sibling to the Damodaran Bot. Each day it screens the S&P 500 through a deterministic moat-quality gate (returns on capital, margin stability, leverage, cash conversion; no LLM involved), so only wonderful businesses reach the watchlist; Claude (Opus/Sonnet) then writes the moat, management, and circle-of-competence read, and Python values owner earnings against a margin of safety to flag the rare “fat pitch” BUY. Research experiment, not investment advice.
buffy.vineai.tech
Reach
Multi-tenant SaaS that runs the entire job hunt on autopilot: it scrapes thousands of postings once into a shared inventory, then per user scores every match, tailors a resume and cover letter to each specific role, and applies, by email or by filling ATS forms directly (Playwright, with an ATS resolver and one-time-code auto-entry from inbound mail), human-review by default. Each user gets a dedicated apply identity on another domain with SES warm-up and inbound routing, making deliverability a first-class feature. A two-tier LLM pipeline runs through a self-hosted gateway (a fast open-weight 120B model scores and extracts, a stronger model writes) behind a grounding validator and humanizer that keep tailored text truthful and free of AI tells. FastAPI · Postgres · React/Clerk; nothing auto-sends until per-user caps and opt-in gates clear.
reach.jobs
Off The List
Multi-tenant privacy service (DeleteMe/Optery class) that finds your personal information across ~1,830 data-broker and people-search sites, gets it taken down, and keeps it down. A scan worker files every hit as an evidenced exposure with a match confidence; removals go out as deterministic CCPA/CPRA deletion notices or guided opt-outs, and a verification loop re-files until listings stay gone; reappearances reopen the case automatically. Confirmation-email brokers are closed out hands-free by a managed opt-out inbox with auto-clicked confirmation links. FastAPI · Postgres · Redis · React · Clerk multi-tenancy.
offthelist.org
CouncilRadar
Civic-intelligence SaaS that monitors municipal council agendas and warns small businesses before the vote, not after it. Scrapers cover seven agenda platforms (Legistar, PrimeGov, CivicClerk, Granicus, CivicPlus, IQM2, eScribe) with failures isolated per municipality; an LLM classifies every agenda item against a ten-industry small-business taxonomy, firing instant email alerts on medium-or-higher impact. First production sweep: 57 municipalities across 25 states, 8,999 agenda items classified with zero scrape failures. FastAPI · Postgres · Redis · React · Clerk · Stripe.
councilradar.org
AI Content Detector
Forensic portal that estimates the probability a piece of content (text, document, image, or video) was AI-generated, with a transparent per-signal evidence breakdown. Independent signals (token-level perplexity and rank, cross-model entropy ratio, an LLM forensic judge, stylometry, C2PA/metadata provenance, and image/video frequency and noise forensics) are fused in logit space so decisive evidence dominates. Runs entirely on self-hosted open-weight models (no third-party detector APIs) and collects ground-truth feedback to retrain and recalibrate.
detector.vineai.tech
AI Chatbot Platform
Multitenant chatbot hosting platform with custom bot builder, RAG knowledge base, SSE streaming, embeddable widget, and Clerk authentication.
chatbots.vineai.tech
Study Buddy
AI-powered tutoring chatbot built on the chatbots platform. Guides students through problems with Socratic questioning, image/camera support, and LaTeX math rendering.
studybuddy.vineai.tech
VineAI Search
Self-hosted privacy-respecting meta-search over 70+ engines. Custom BM25 + domain trust + MMR ranking pipeline with optional self-hosted AI answers streamed from a 120B-parameter vLLM model, with no third-party AI dependencies.
search.vineai.tech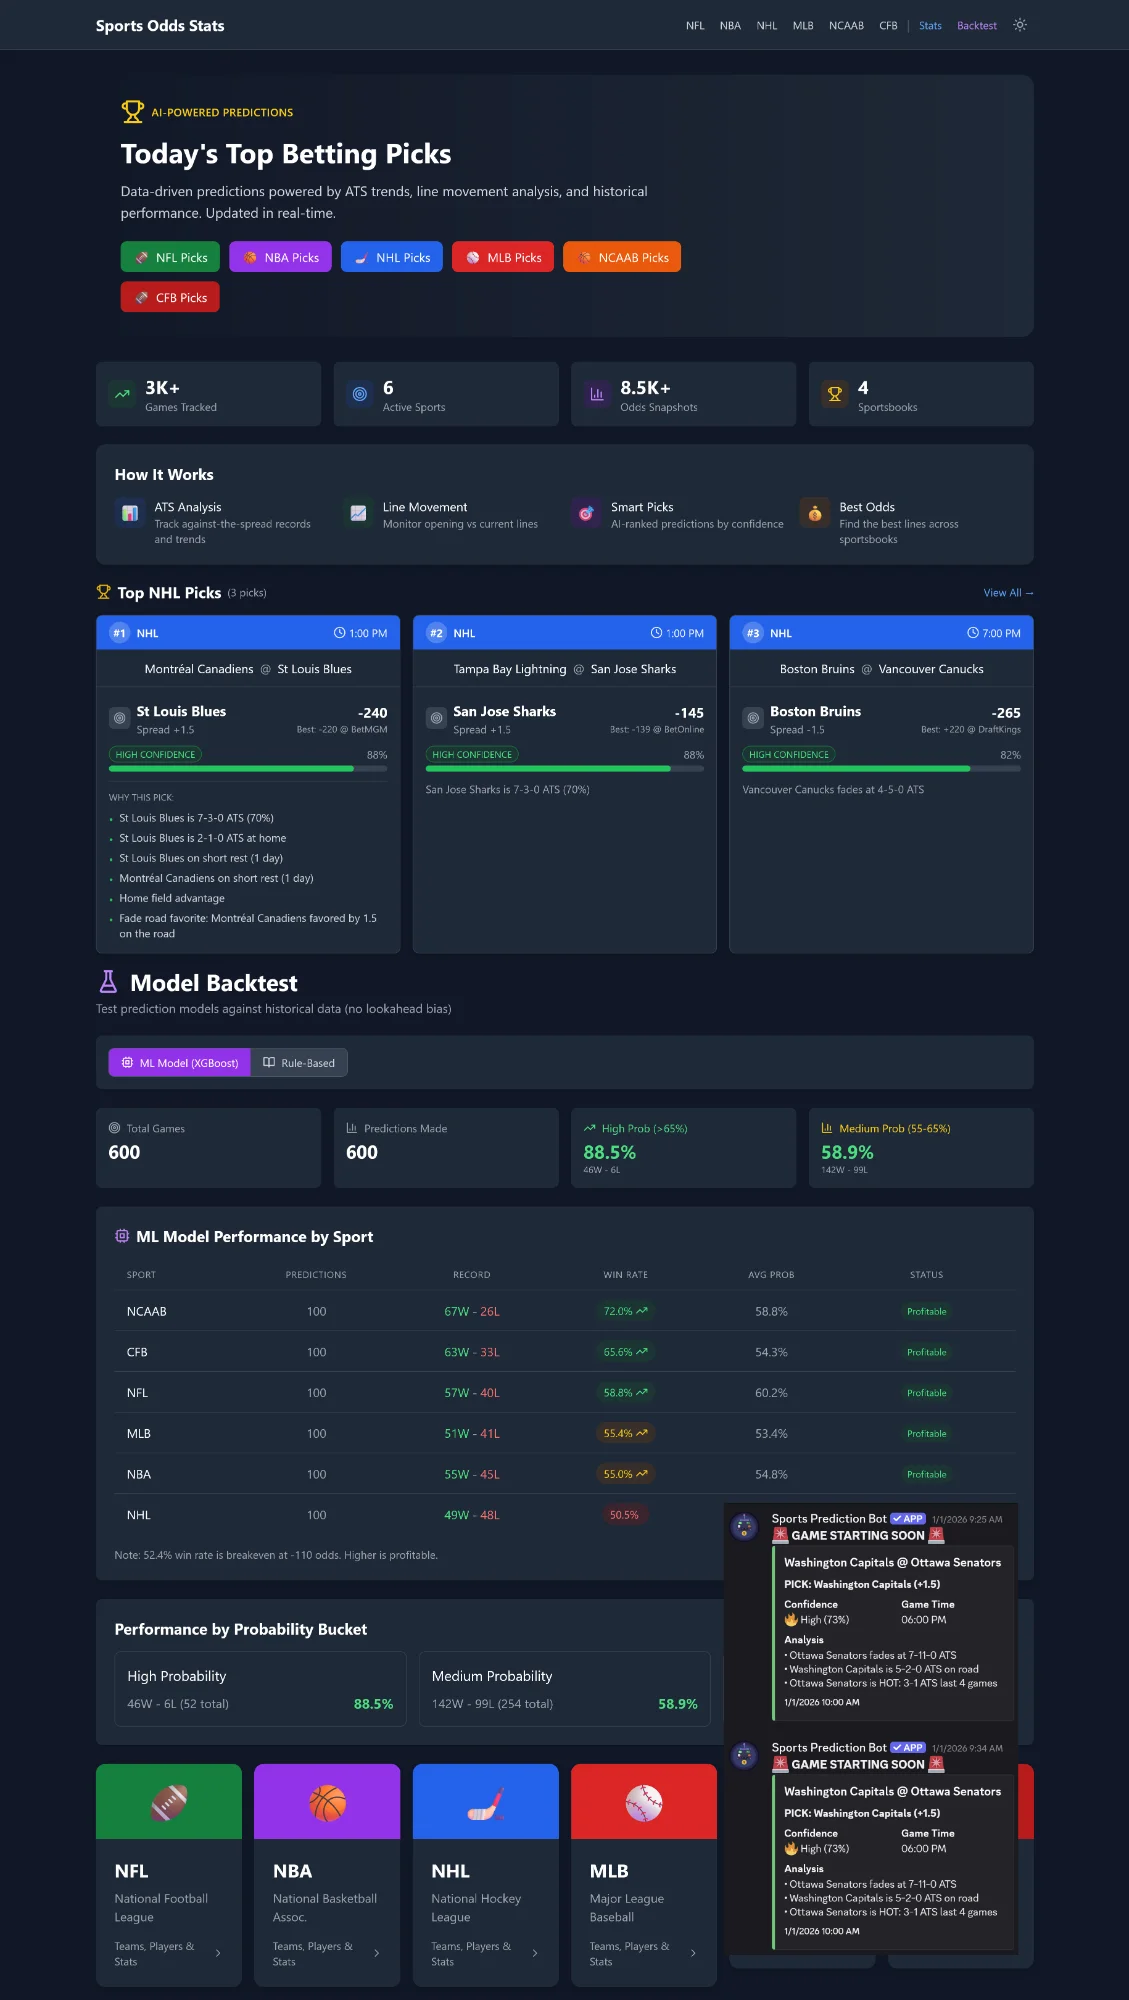
Sports Analytics
Full-stack platform covering NFL, NBA, NHL, MLB, CFB, and NCAAB with AI-powered predictions, multi-sportsbook odds comparison, and Discord bot integration.
sports.vineai.tech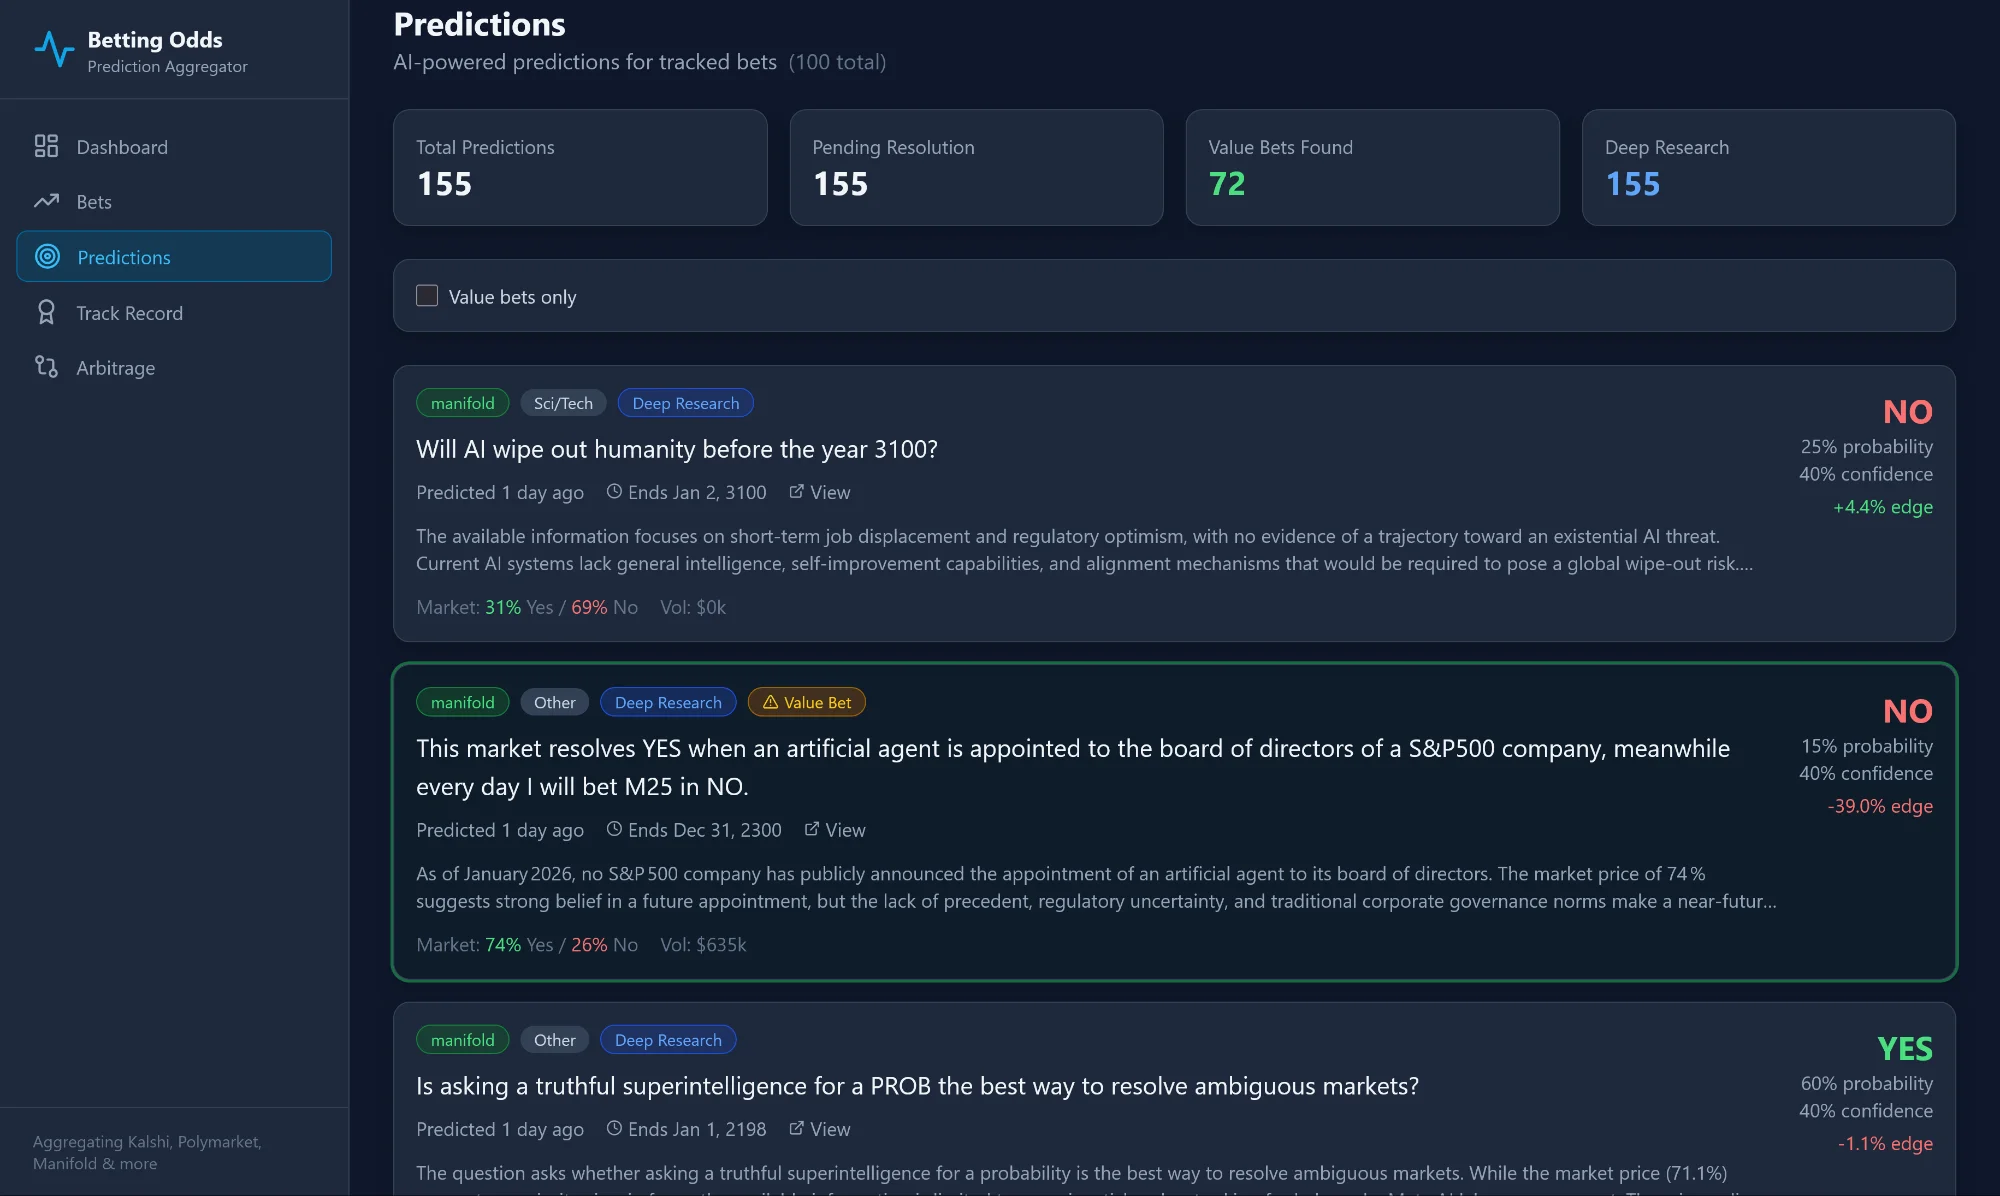
Prediction Markets
AI forecasting platform aggregating Kalshi, Polymarket, Manifold, and PredictIt with cross-platform arbitrage detection.
betting.vineai.tech
Podbay
Open-source runtime contract layer for Podman stacks, written in Go. Declarative contracts with preflight validation, deterministic deploys with receipts, and drift detection: shared operational truth for humans and AI agents.
github.com/1eve1Up/podbay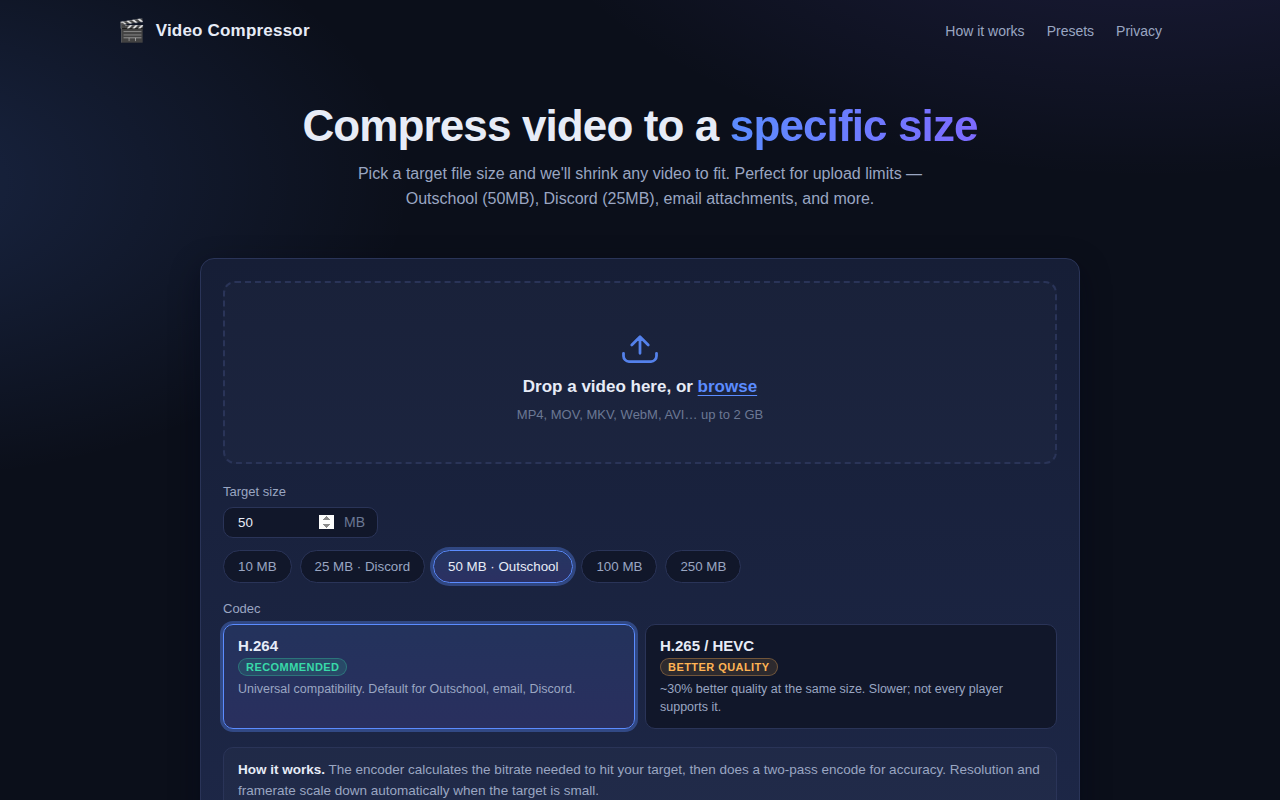
Video Compressor
Target-size video compressor: pick a file size and it hits it. Two-pass H.264/H.265 encoding with automatic resolution and framerate scaling, chunked uploads up to 2 GB, and self-cleaning storage.
converter.vineai.tech
About
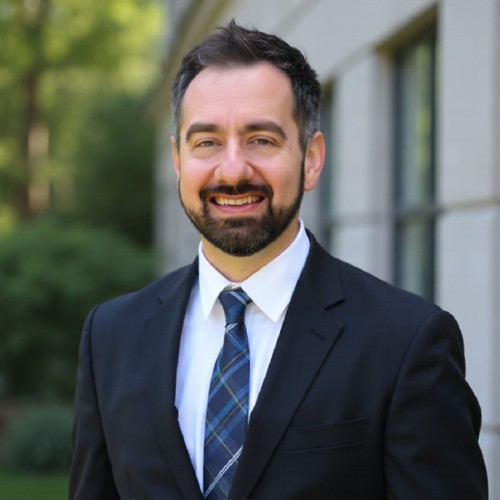
Results-driven technologist with 15+ years architecting enterprise infrastructure and automation solutions. Currently pursuing an MS in Computer Science (Machine Learning) at Georgia Tech while building AI-driven automation for finance and consumer applications. Works forward-deployed: embedded with client teams, shipping on their infrastructure, from a fully on-premises GPU platform to a client-owned Azure tenant, and handing over documented, operable systems.